Skip to content
Back to all articles
AI & automationJuly 16, 2026 · 11 min read

Automation only works where the process repeats

Why automation is built on repetition, how AI agents expanded the range of tasks a machine can take over, what should stay with humans, and the one spreadsheet every business should build first.
Abstract illustration of connected gears and data flows representing process automation

Conversations about automation drown in terminology fast: integrations, RPA, AI agents, low-code. Underneath all of it sits one simple mechanism. You spend effort once to describe and set up a process, and from then on it runs by itself — dozens, hundreds, thousands of times. The setup is expensive; every subsequent run costs almost nothing. That gives you the key criterion for deciding what to automate at all: the process has to repeat. Often, and in roughly the same way. If a task comes up once a quarter and looks different every time, automation won't pay for itself, no matter how fashionable the technology.

This is remarkably similar to how our own brains work. When you learn to drive, every gear change demands attention. Six months later your hand does it on its own, and your attention is free for the road. The brain noticed a repeating action and turned it into a reflex. Business automation does exactly the same thing, except the reflexes live in the company's software instead of an employee's head. And just as the brain doesn't build a reflex for something you did once, a business shouldn't automate what doesn't repeat.

Traditional automation: exact steps, many repetitions

Classic software automation requires the process to be fully formalizable: specific steps, specific conditions, a specific result. A request arrives from the website — create a CRM card and assign a manager. A deal status changes — send the customer an email. It's the first of the month — export the report and drop it in the shared folder. Where a system has no convenient API, a software robot can repeat the same actions directly in the interface: moving data between windows, filling forms, downloading exports.

This kind of automation has an honest limitation: it does exactly what it was told, and nothing more. That is both its weakness and its strength. A weakness, because any deviation from the script breaks it. A strength, because on its home turf it works reliably, cheaply, and predictably — no hallucinations, no creative interpretations. If an employee performs the same routine by the same algorithm twenty times a day, that's a perfect candidate for plain software automation, and there is no reason to drag neural networks into it.

AI agents: when the process is similar but not identical

Neural networks expanded the automation field in an important direction: the process no longer has to be identical every time. It's enough for it to be roughly the same — at the level of how the task is phrased. Customer emails are all different, but the task «read the email, understand what it's about, extract the data for a request» repeats unchanged. Supplier documents arrive in different formats, but the task «find the amount, dates, and payment details in the document» is always the same. These processes used to be considered impossible to automate, because you can't write a rigid rule for them. Now you write a prompt.

You can hand an AI agent fairly deep tasks too: draft a reply to a customer, parse an incoming document, produce a first summary of a long thread. But that comes with a mandatory condition — validation stays with a human. AI makes mistakes, and it makes them confidently, so its output needs checking. And here's the part that matters: the check has to be easy. If an employee has to re-read everything the agent produced from start to finish, you saved nothing — you just swapped one job for another. Well-designed automation shows the person a short summary, highlights the places where the agent is unsure, and lets them accept or reject the result in a couple of clicks. The difference between «read three pages» and «glance at five lines and press a button» is the difference between automation people use and automation people quietly sabotage.
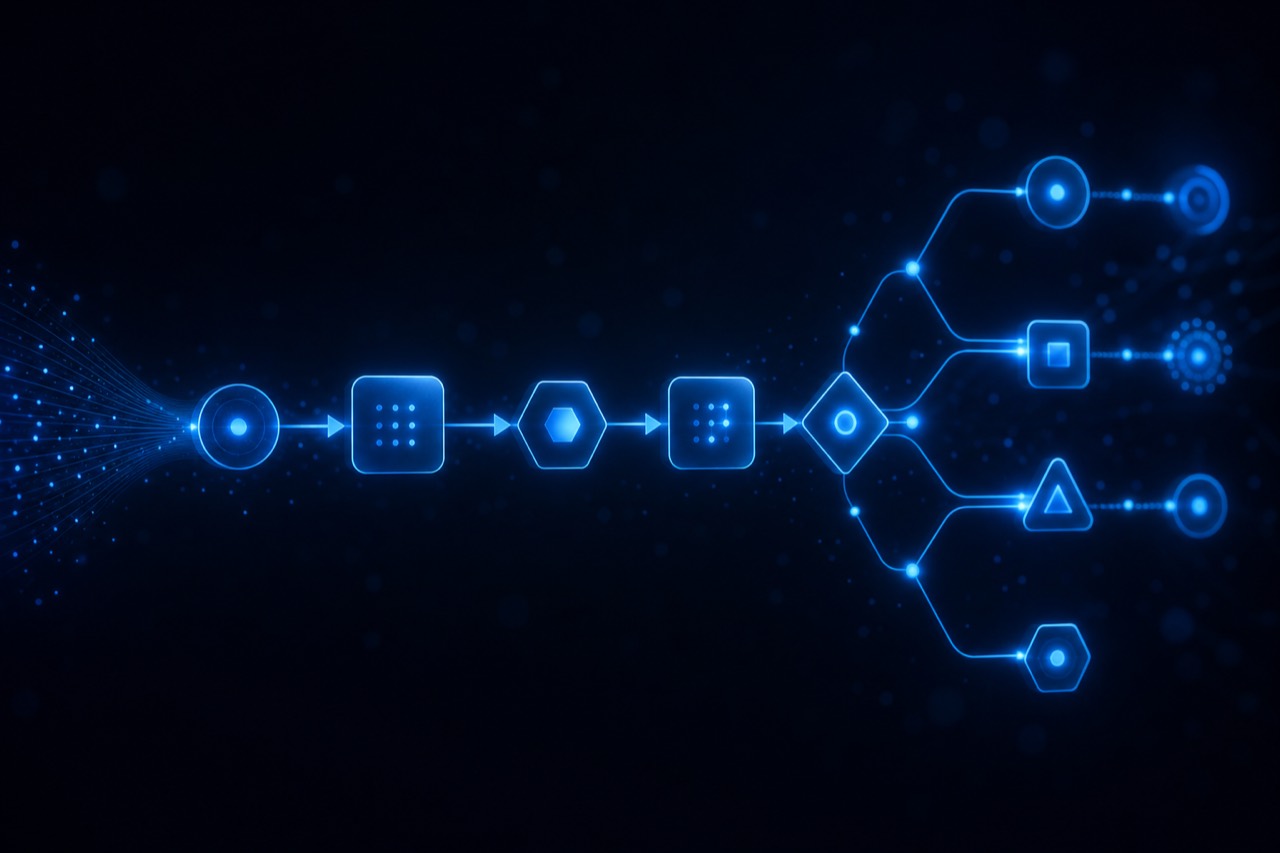
Diagram of an automated process: an input, sequential processing steps, and branching into several outcomes

What you still can't hand to the machine

There is a line AI shouldn't cross today: multi-step reasoning. Tasks like «analyse the situation, weigh the options, account for context that isn't written down anywhere, and make a decision» are unreliable for models — an error at step two silently propagates through everything that follows, and the output is a convincing, well-formatted, wrong conclusion. Deep analysis and consequential decisions are better left to people.

At the same time, a person with AI at hand gets noticeably more done. Any complex job is full of subtasks that require no real intelligence but eat time: finding the right fragment in a forty-page document, consolidating numbers from three emails into one table, sketching the structure of a report. An analyst used to lose half a day to this; now it takes minutes. The reasoning and the decisions are still theirs, but the machine handles the grunt work. That's the right frame for the next few years: AI removes the low-intelligence routine around a hard task rather than replacing the person solving it.

You can't automate chaos

The most persistent deployment mistake is trying to automate a process that doesn't really work even manually. If requests get lost because nobody knows who owns them, a robot won't save you: it will dutifully keep passing them into the void, just faster. A broken process becomes a fast broken process after automation. First put things in order by hand — agree on the steps, the owners, and the rules — and only then lock that order into software.

Automating chaos just gives you chaos at speed. First describe and simplify the process, and only then hand it over to robots and agents.

The second mistake from the same family is taking on everything at once. A big «automate the whole company» project delivers nothing for months, burns through budget and enthusiasm, and then quietly dies. A pilot on one frequent process shows results in weeks, and those results become the argument for the next step. It's boring advice, but it keeps outperforming every ambitious plan.

A tool without a feedback loop dies

The third mistake gets talked about less, which is a shame: tools get built without a feedback channel. Automation breaks quietly — an export format changes and the robot stalls; customers start asking about a new product and the bot answers nonsense. If users have nowhere to report a problem, you'll learn about it a month later, from declining numbers, and by then people will have gone back to doing the work by hand.

The cure costs next to nothing: a feedback channel built right into the tool. A thumbs-down under the bot's answer. A «what went wrong?» field next to the agent's output. A «report a problem» button in the form. The easier it is to leave feedback, the more often people leave it, and every piece of it is a concrete pointer to what to fix and what to add. A team that sees a live stream of «the bot got this one wrong» iterates faster than one that commissions a survey once a quarter. This applies equally to software automation and to AI: for the former, feedback catches broken scenarios; for the latter, gaps in knowledge and prompts. In both cases the loop of «complaint — fix — check» directly drives the very numbers the automation was built for.

The spreadsheet a business can build itself

Before calling a contractor or hiring developers, there is one thing worth doing that requires no technical background at all — building a spreadsheet of your processes. In the rows, everything the company does regularly: handling requests, issuing invoices, answering typical questions, assembling reports, approvals. In the columns, the things only you know:

  • how often the process runs — hourly, daily, weekly;
  • how long it takes and whose time it takes;
  • what it costs — in staff hours and in money, including the cost of errors;
  • how formalized it is — a clear algorithm, a rough «this is usually how we do it», or improvised every time.

You don't need to estimate implementation costs at this stage — that is exactly the job for AI and IT specialists, who will look at your spreadsheet and tell you what a simple week-long integration can cover, where an agent with validation is needed, and what is still cheaper to leave to people. But the initial picture — which processes exist and what they cost — can only be assembled by the business itself. That spreadsheet turns the conversation with a contractor from «we want something with AI» into a concrete calculation: here's a process, it costs us forty hours a month, what can be done about it and for how much. Usually the starting point becomes obvious while you're still filling it in.

Where to start

Build the process spreadsheet, pick one process from it — frequent, expensive, and at least roughly formalized — and take its automation to a stable result with human validation and simple feedback. In a couple of weeks you'll have numbers on your own data instead of gut feelings, and the next step will be obvious. If you'd like to get there faster, show us your spreadsheet or just tell us what's eating your team's time — we'll propose a solution and a subscription estimate.

Legal documents

Privacy Policy

Effective date: June 10, 2026


This Privacy Policy explains how Pyramind, a sole proprietorship (preduzetnik) registered in the Republic of Serbia (the “Operator”, “we”, “us”), processes personal data of visitors and prospective clients of the website https://pyramind.tech (the “Site”) and of users of products developed by Pyramind under separate subscription agreements.

This document is drafted to comply with the Serbian Law on Personal Data Protection (Zakon o zaštiti podataka o ličnosti, “ZZPL”) and to align with Regulation (EU) 2016/679 (GDPR), the UK GDPR and DPA 2018, the Brazilian LGPD (Law No. 13.709/2018), the Swiss revised FADP, and the California CPRA to the extent applicable to our processing.

A separate Russian-language policy (/legal/politika-obrabotki-pd.md) governs processing performed by our Russian affiliate (Sole Proprietor Dmitrii Litvinenko, RU) for Russian-resident clients under a separate contractual setup.

1. Controller and contact

  • Operator (controller): Pyramind, sole proprietorship (preduzetnik) registered in the Business Registers Agency of the Republic of Serbia (APR).
  • Registered name: [REGISTERED NAME — to insert]
  • PIB (tax ID) / matični broj (registration number): [to insert]
  • Registered seat: [address], Republic of Serbia
  • Email for privacy enquiries: dev@pyramind.tech
  • EU/UK Article 27 representative: to be appointed in writing before active marketing in the EU/UK and listed here. Until appointment, please direct all enquiries to dev@pyramind.tech.
  • Data Protection Officer: not appointed; under GDPR Art. 37 / ZZPL Art. 56 not strictly required at the current scale of processing. We will reassess this if processing volume or sensitivity changes.

2. Personal data we process

We process the following categories of personal data:

  • Contact data you submit through forms or by emailing us: name, business email, phone number, company name, company URL, preferred contact method (call / Telegram / WhatsApp), free-form message.
  • Technical data automatically collected when you browse the Site: IP address, user-agent, referrer, time-zone, language, device and browser characteristics, pages viewed, events triggered. This data is collected only after analytics consent for non-essential cookies (see Section 6).
  • Communication data: emails, messages, transcripts of voice or video calls if you initiate them. We record calls only with your prior explicit consent.
  • Account / contractual data for clients under a Subscription Agreement: legal entity details, signatory names, billing data, invoice records.

We do not intentionally collect special categories of data (Art. 9 GDPR / Art. 17 ZZPL), data of children under 16 (Art. 8 GDPR), or biometric data via the Site. If you submit such data voluntarily through a free-form field, we will minimise and erase it.

3. Purposes and lawful bases

PurposeLawful basis (GDPR Art. 6 / ZZPL Art. 12)
Responding to enquiries, sending proposals, conducting pre-contractual negotiations(b) steps prior to entering into a contract; (f) legitimate interest in B2B outreach
Performance of a Subscription Agreement and related services(b)
Site analytics, performance monitoring, A/B testing(a) consent (granular, withdrawable); (f) for strictly necessary security telemetry
Marketing newsletters and re-engagement(a) opt-in consent (no soft opt-in for non-customers)
Compliance with tax, accounting, AML, sanctions screening, court orders(c) legal obligation; (f) legitimate interest in fraud and sanctions risk control
Defending legal claims(f); (e) under Serbian public-interest grounds where applicable

For California residents, the corresponding business purposes under the CPRA are: providing services, performing contracts, security and integrity, debugging, internal research, and limited marketing.

4. Recipients and processors

We share personal data with the following categories of recipients:

  • Hosting and infrastructure providers — by default within the European Economic Area or the Republic of Serbia. For products delivered to clients in other regions, we may, with the client's prior agreement, use a regional cloud (UAE, Singapore, etc.).
  • Email and messaging providers for replying to your enquiries (transactional email, Telegram, WhatsApp Business).
  • Analytics providers — Yandex LLC (Yandex Metrica), only if you have given analytics consent. Yandex Metrica processes data in the Russian Federation; see Section 5.
  • Payment, banking, and accounting service providers in the Republic of Serbia and, where applicable, in the recipient's country.
  • Professional advisors — lawyers, auditors, tax advisors — under written confidentiality.
  • Authorities — when required by Serbian law, EU/EEA law applicable through SCCs, court order, or to protect our rights.

A current list of our sub-processors for product clients is published as a separate document; see `/legal/en/sub-processors.md`.

5. International data transfers

The Operator is established in the Republic of Serbia. Serbia is not an EU member state and is not subject to a current adequacy decision under GDPR Art. 45. However, the Serbian Commissioner for Personal Data Protection has confirmed Serbian DP law as substantially aligned with the GDPR, and Serbia is on the Council of Europe Convention 108+.

For transfers from the EEA, UK, or Switzerland to Serbia we rely on:

  • Standard Contractual Clauses (SCCs) under Commission Implementing Decision (EU) 2021/914 with supplementary measures (encryption in transit and at rest, access controls, audit logging) for ongoing engagements;
  • Your explicit, informed consent under Art. 49(1)(a) GDPR for one-off interactions where appropriate;
  • Contractual necessity under Art. 49(1)(b) where the transfer is necessary for the performance of, or the conclusion of, a contract you requested.

Where analytics consent is granted, technical data may be transmitted to Yandex (Russian Federation). Russia is not subject to an adequacy decision; we rely on your explicit consent (GDPR Art. 49(1)(a)) for this transfer, with the disclosure that Russian law may grant authorities access to data without remedies equivalent to EU standards.

6. Cookies and similar technologies

The Site uses cookies and similar technologies in three categories: strictly necessary, analytics, and marketing. Analytics and marketing cookies do not load until you give consent through our cookie banner (all non-essential storage defaults to denied). Detailed information on each cookie, retention periods, and opt-out controls is set out in our Cookie Policy.

You can withdraw or change cookie consent at any time via the “Manage cookies” link in the footer or on this page.

7. Retention

We retain personal data only for as long as necessary for the purpose of processing, then delete or anonymise it.

  • Enquiry contacts (no contract concluded): up to 12 months from last contact, then deleted.
  • Client contractual records: for the duration of the Subscription Agreement and 3 years after termination, plus the longer of (i) the statutory accounting and tax retention period under Serbian law (5 years for primary accounting books, 10 years for invoicing records, per the Serbian Accounting Law) and (ii) any retention required under your local law.
  • Analytics data: as configured in the analytics provider (default 25 months for Yandex Metrica, unless you withdraw consent earlier).
  • Marketing consents: until you withdraw consent or for 3 years from last engagement, whichever is earlier.

8. Your rights

Subject to applicable law, you have the right to:

  • Access the personal data we hold about you (GDPR Art. 15 / ZZPL Art. 26 / UK GDPR / LGPD Art. 18 / CPRA §1798.110);
  • Rectify inaccurate or incomplete data (Art. 16 / ZZPL Art. 29);
  • Erase data (“right to be forgotten”) (Art. 17 / ZZPL Art. 30);
  • Restrict processing (Art. 18 / ZZPL Art. 31);
  • Data portability in a structured, commonly used, machine-readable format (Art. 20 / ZZPL Art. 36);
  • Object to processing based on legitimate interests, including profiling (Art. 21 / ZZPL Art. 37), and, in particular, to direct marketing at any time;
  • Withdraw consent at any time, without affecting prior lawful processing (Art. 7(3) / ZZPL Art. 15);
  • Not be subject to a decision based solely on automated processing producing legal effects (Art. 22 / ZZPL Art. 38). We do not use such processing.
  • For California residents: the right to know, delete, correct, opt out of sale or sharing, and limit the use of sensitive personal information (we do not “sell” personal data within the meaning of CPRA §1798.140(ad), but we will honour Global Privacy Control (GPC) signals).
  • For Brazilian data subjects: the rights enumerated in LGPD Art. 18.

To exercise rights, email dev@pyramind.tech. We will respond within 30 days (GDPR/UK/LGPD/ZZPL) or 45 days (CPRA), with one possible extension as permitted by law. We may need to verify your identity before disclosing or modifying data.

You also have the right to lodge a complaint with a supervisory authority — the Serbian Commissioner for Information of Public Importance and Personal Data Protection (Poverenik za informacije od javnog značaja i zaštitu podataka o ličnosti) for matters under our remit; your local data protection authority in the EEA / UK; the ANPD in Brazil; or the California Attorney General / CPPA.

9. Security

We implement organisational and technical measures appropriate to the risk under Art. 32 GDPR / Art. 42 ZZPL, including encryption of data in transit, access controls, audit logging, regular backups with restoration testing, vulnerability management, and incident response procedures. In the event of a personal data breach affecting your data, we will notify the Serbian Commissioner within 72 hours where required, and notify you without undue delay where required by law.

10. Automated decision-making and profiling

We do not engage in automated decision-making producing legal or similarly significant effects on you (GDPR Art. 22 / ZZPL Art. 38). Where products we develop for clients embed AI/ML features, the client (controller) is responsible for compliance with Art. 22, the EU AI Act (Regulation (EU) 2024/1689), and equivalent provisions; we act as processor under a separate Data Processing Agreement.

11. Children

The Site is not directed to children under 16. We do not knowingly collect personal data from children. If you believe we have collected such data, please contact us and we will delete it.

12. Changes to this Policy

We will publish updates to this Policy on this page with a new effective date. Material changes will be highlighted at the top of the page for at least 30 days, and we will notify clients with a current Subscription Agreement by email.

13. Contact

For all privacy-related enquiries, requests, or complaints:

  • Email: dev@pyramind.tech
  • Postal address: [address], Republic of Serbia (available on request from the email above for service of formal legal correspondence).

This Privacy Policy is provided for information only and does not, by itself, replace contractual or statutory protections. In case of conflict between this English text and any local-language version, the English text governs for all data subjects outside the Russian Federation; for Russian-resident data subjects whose data is processed by our Russian affiliate, the Russian-language /legal/politika-obrabotki-pd.md prevails.